High-volume web data collection

Async Scraper Service

Submit large public-web data jobs asynchronously and retrieve results when they are ready. Struqter handles concurrency, adaptive access, retries, and rendering behind one API workflow.

  • High-volume asynchronous jobs
  • Adaptive anti-bot handling
  • Status-based result retrieval
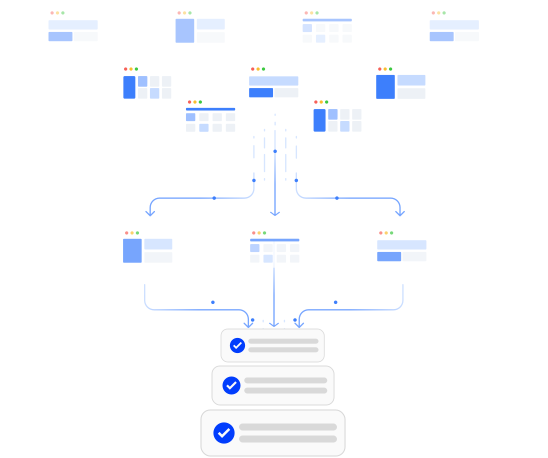
Struqter coordinates website requests and returns structured results

Built for teams collecting public web data at scale

  • Boltshift
  • Lightbox
  • FeatherDev
  • Spherule
  • Globan

Managed asynchronous collection

Operate large scraping jobs without the infrastructure burden

Separate submission from processing and delivery while Struqter handles the access work behind each request.

Scrape Data at Scale Across Public Websites

Submit large web data jobs without keeping client connections open for every request.

Struqter manages concurrency, retries, and access strategy in the background so collection can continue as targets respond.

Discuss your workload
Collect from Hard-to-Scrape Websites

Dynamic rendering, regional responses, blocks, and request limits make some public sites harder to collect from reliably.

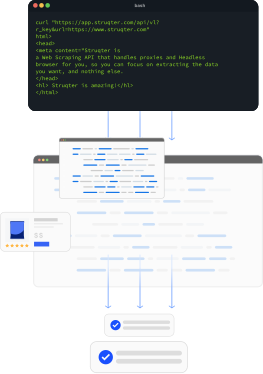
Struqter applies the proxy, browser, headers, and retry strategy suited to each request without adding those systems to your stack.

Discuss your targets

Focus on Data, Not Concurrency

Send the URLs and collection requirements once, then let the async workflow coordinate parallel processing and recovery.

Your application can keep doing useful work instead of holding open connections or maintaining its own job queue.

Plan your integration

Submit Once. Retrieve Results When Ready.

Each accepted job returns a status reference your application can use to check progress and retrieve the completed result.

This separates submission from delivery, making long-running and high-volume collection easier to operate.

Talk through the workflow

When asynchronous scraping helps

When to Use an Async Scraper API

Async collection is useful when request volume, target difficulty, or processing time makes one open connection per page impractical.

Improve Success Rates

Apply rendering, location, headers, and retries according to what each target requires.

Control Failure Spikes

Move retry and recovery logic out of your application when targets become slower or more restrictive.

Handle Difficult Targets

Use managed access strategies for public sites that need more than a basic HTTP request.

Process Large URL Sets

Run sustained collection workloads without building a separate queue, proxy pool, or browser fleet.

Business value

Turn web data infrastructure into product momentum

Improve Response Time and Success Rates

Collect more data with fewer failed jobs by applying an access strategy matched to the target instead of treating every request the same.

Discuss performance

Give Engineering Time Back to the Product

Keep your team focused on using web data rather than maintaining proxy rotation, browser infrastructure, CAPTCHA handling, retries, and job orchestration.

Review your setup

Find the Right Price-to-Value Combination

Connect Struqter to the workflows you already own and scale collection around the targets, frequency, and output your product actually needs.

Scope a solution

Designed for demanding workloads

Enterprise-level collection without operating the stack yourself

  • Coordinate large URL sets asynchronously
  • Get direct help with targets and integration
  • Keep access and recovery logic out of your product
Asynchronous High-volume request handling
Status-based Submission and result retrieval
Structured HTML or analysis-ready output